 PluginStats
spark pulls statistics
Apache Spark - A unified analytics engine for large-scale data processing
spark has 2,096,924 recorded pulls on Docker Hub.
It ranks #219 of 1,263 tracked Docker Hub listings by pulls.
PluginStats has 3 daily observations since Oct 16, 2026; the latest is from Oct 18, 2026.
About spark
Quick reference
• Maintained by: Apache Spark • Where to get help: Apache Spark™ community
Supported tags and respective Dockerfile links
• 4.2.0-scala2.13-java21-python3-ubuntu, 4.2.0-java21-python3, 4.2.0-python3, 4.2.0, python3, latest • 4.2.0-scala2.13-java21-r-ubuntu, 4.2.0-java21-r, 4.2.0-r, r • 4.2.0-scala2.13-java21-ubuntu, 4.2.0-java21-scala, 4.2.0-scala, scala • 4.2.0-scala2.13-java21-python3-r-ubuntu • 4.2.0-scala2.13-java17-python3-ubuntu, 4.2.0-java17, python3-java17 • 4.2.0-scala2.13-java17-r-ubuntu, 4.2.0-java17-r, r-java17 • 4.2.0-scala2.13-java17-ubuntu, 4.2.0-scala-java17, scala-java17 • 4.2.0-scala2.13-java17-python3-r-ubuntu • 4.2.0-scala2.13-java25-python3-ubuntu, 4.2.0-java25, python3-java25 • 4.2.0-scala2.13-java25-r-ubuntu, 4.2.0-java25-r, r-java25 • 4.2.0-scala2.13-java25-ubuntu, 4.2.0-scala-java25, scala-java25 • 4.2.0-scala2.13-java25-python3-r-ubuntu • 4.1.3-scala2.13-java21-python3-ubuntu, 4.1.3-java21-python3, 4.1.3-java21 • 4.1.3-scala2.13-java21-r-ubuntu, 4.1.3-java21-r • 4.1.3-scala2.13-java21-ubuntu, 4.1.3-java21-scala • 4.1.3-scala2.13-java21-python3-r-ubuntu • 4.1.3-scala2.13-java17-python3-ubuntu, 4.1.3-java17, 4.1.3-python3, 4.1.3 • 4.1.3-scala2.13-java17-r-ubuntu, 4.1.3-java17-r, 4.1.3-r • 4.1.3-scala2.13-java17-ubuntu, 4.1.3-scala-java17, 4.1.3-scala • 4.1.3-scala2.13-java17-python3-r-ubuntu • 4.0.4-scala2.13-java21-python3-ubuntu, 4.0.4-java21-python3, 4.0.4-java21 • 4.0.4-scala2.13-java21-r-ubuntu, 4.0.4-java21-r • 4.0.4-scala2.13-java21-ubuntu, 4.0.4-java21-scala • 4.0.4-scala2.13-java21-python3-r-ubuntu • 4.0.4-scala2.13-java17-python3-ubuntu, 4.0.4-python3, 4.0.4 • 4.0.4-scala2.13-java17-r-ubuntu, 4.0.4-r • 4.0.4-scala2.13-java17-ubuntu, 4.0.4-scala • 4.0.4-scala2.13-java17-python3-r-ubuntu • 3.5.9-scala2.12-java17-python3-ubuntu, 3.5.9-java17-python3, 3.5.9-java17 • 3.5.9-scala2.12-java17-r-ubuntu, 3.5.9-java17-r • 3.5.9-scala2.12-java17-ubuntu, 3.5.9-java17-scala • 3.5.9-scala2.12-java17-python3-r-ubuntu • 3.5.9-scala2.12-java11-python3-ubuntu, 3.5.9-python3, 3.5.9 • 3.5.9-scala2.12-java11-r-ubuntu, 3.5.9-r • 3.5.9-scala2.12-java11-ubuntu, 3.5.9-scala • 3.5.9-scala2.12-java11-python3-r-ubuntu
Quick reference (cont.)
• Where to file issues: https://issues.apache.org/jira/browse/SPARK • Supported architectures: (more info) amd64, arm64v8 • Published image artifact details: repo-info repo's repos/spark/ directory (history) (image metadata, transfer size, etc) • Image updates: official-images repo's library/spark label official-images repo's library/spark file (history) • Source of this description: docs repo's spark/ directory (history)
What is Apache Spark™?
Apache Spark™ is a multi-language engine for executing data engineering, data science, and machine learning on single-node machines or clusters. It provides high-level APIs in Scala, Java, Python, and R, and an optimized engine that supports general computation graphs for data analysis. It also supports a rich set of higher-level tools including Spark SQL for SQL and DataFrames, pandas API on Spark for pandas workloads, MLlib for machine learning, GraphX for graph processing, and Structured Streaming for stream processing.
Online Documentation
You can find the latest Spark documentation, including a programming guide, on the project web page. This README file only contains basic setup instructions.
Interactive Scala Shell
The easiest way to start using Spark is through the Scala shell:
Try the following command, which should return 1,000,000,000:
Interactive Python Shell
The easiest way to start using PySpark is through the Python shell:
And run the following command, which should also return 1,000,000,000:
Interactive R Shell
The easiest way to start using R on Spark is through the R shell:
Running Spark on Kubernetes
https://spark.apache.org/docs/latest/running-on-kubernetes.html
Configuration and environment variables
See more in https://github.com/apache/spark-docker/blob/master/OVERVIEW.md#environment-variable
License
Apache Spark, Spark, Apache, the Apache feather logo, and the Apache Spark project logo are trademarks of The Apache Software Foundation.
Licensed under the Apache License, Version 2.0.
As with all Docker images, these likely also contain other software which may be under other licenses (such as Bash, etc from the base distribution, along with any direct or indirect dependencies of the primary software being contained).
Some additional license information which was able to be auto-detected might be found in the repo-info repository's spark/ directory.
As for any pre-built image usage, it is the image user's responsibility to ensure that any use of this image complies with any relevant licenses for all software contained within.
Description from the Docker Hub listing.
Where spark sits in the listing
Each band is one page of 20. Pulls on a log scale. Placement is projected from pulls, so it can differ from the marketplace's own sort order. Hover a dot to see the listing.


Charts
Images: 30d · 1y · all time · 1600×900 dark
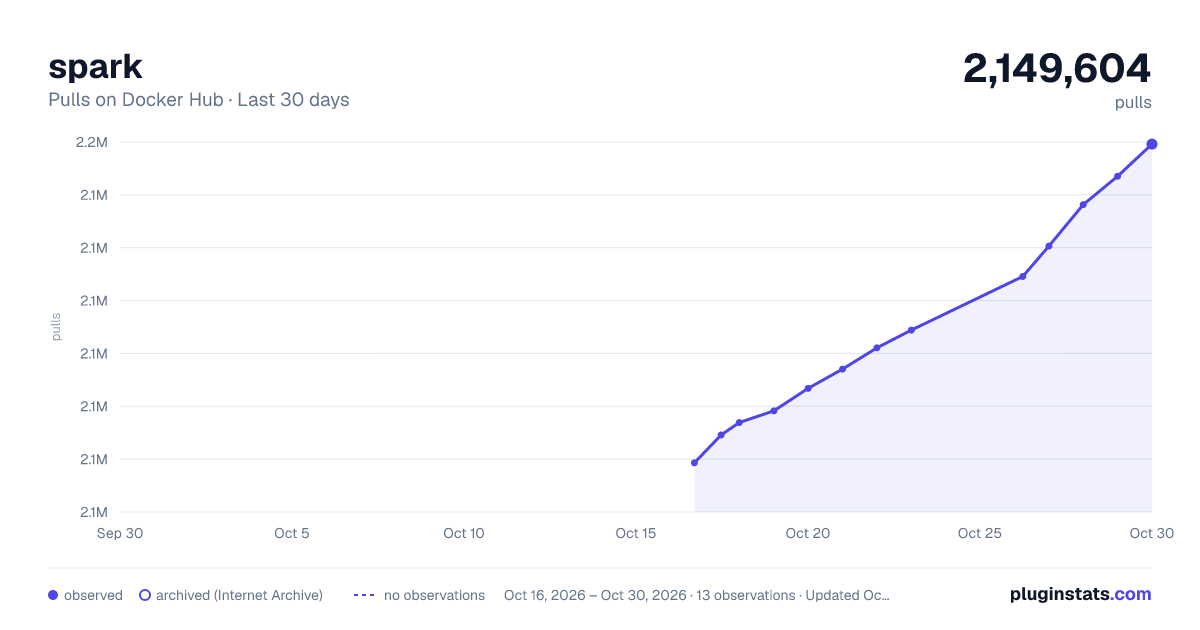
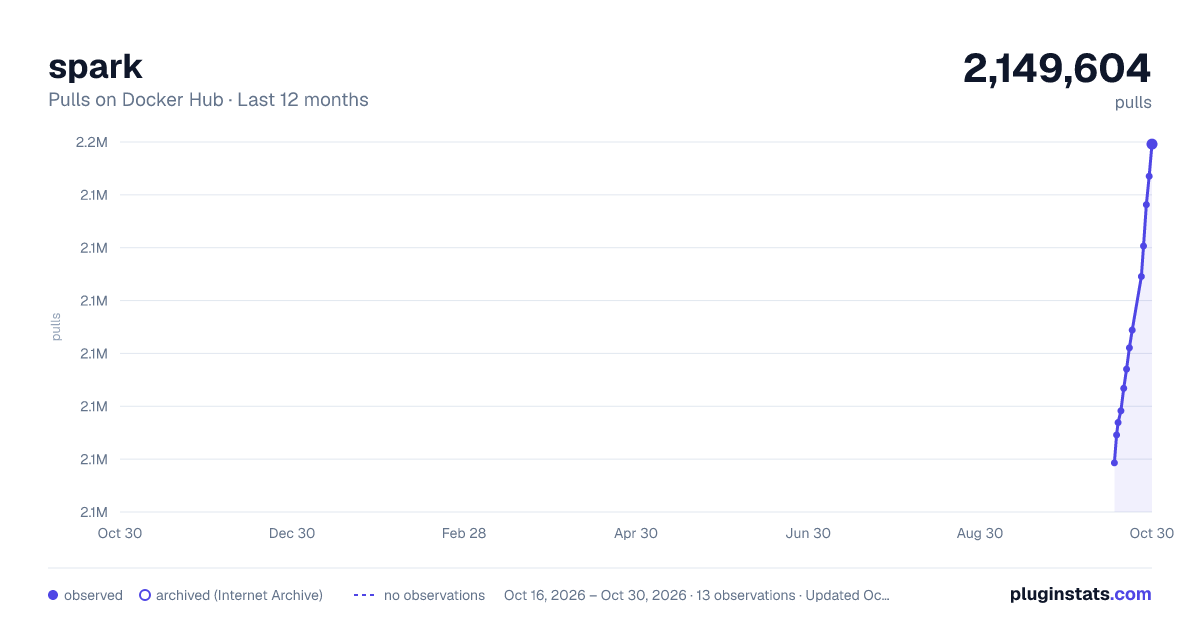
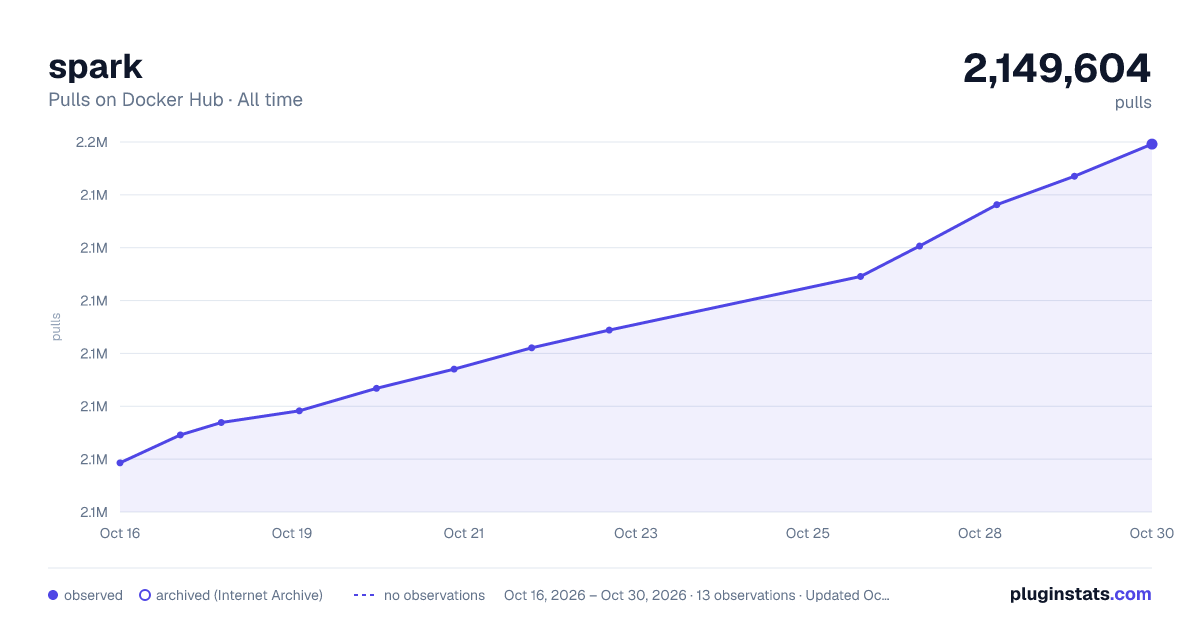

Adoption over time


7/30/90-day growth


Filled points are observed values; hollow points come from Internet Archive snapshots of the listing page. Dashed segments span periods with no observations — values between points are not interpolated.
Recent observations
Full history (3)Similar Docker Hub Data science plugins
Data source
Cumulative pull counts and stars come from the public Docker Hub API. Pulls count image downloads (including automated CI pulls), not installs or users.
Listing: https://hub.docker.com/_/spark. First seen Oct 16, 2026; last successful collection Oct 18, 2026. See the methodology.