 PluginStats
@browserless/agent weekly downloads statistics
By browserless · npm · AI SDKs
Drive a Puppeteer page toward a natural-language goal using finite decisions.
@browserless/agent has 229 recorded weekly downloads on npm.
It ranks #1576 of 2,251 tracked npm listings by weekly downloads.
Over the past 7 days it changed by -91.8%.
PluginStats has 121 daily observations since Jun 19, 2026; the latest is from Oct 17, 2026.
About @browserless/agent
@browserless/agent
Drive an existing Puppeteer page toward a natural-language goal. The caller owns navigation, browser setup, screenshots and closing the browser. This package does not change @browserless/ai, which uses Chrome's built-in AI APIs.
Experimental. It has completed a live Wallapop search (see below), but done is the model's own judgment and runs are not fully reliable.
Usage
Requires Node.js >=24. After the package is published:
agent(page, defaults?) adds two methods to the Puppeteer page it is given and returns the same page:
• page.goal(goal, options?) drives the page, over as many steps as it takes, until the model reports the goal is met. • page.extract(...) returns data from the current page. It does not navigate.
defaults apply to both; options passed to a call override them, and an option passed as undefined or null keeps the default. The same functions are exported for use without touching the page: agent.goal(page, …) and agent.extract(page, …).
Import compatibility is CommonJS plus the Node ESM default import, with TypeScript declarations.
From the browserless CLI
browserless exec from @browserless/cli opens a page and passes it to the function the file exports, so the script does not manage the browser:
A goal or an extraction that fails does not throw: the script gets status: 'error' with error and decides what to do. The CLI exits with code 1 only when the script itself throws, so a script that should fail the command throws that error.
Examples
Every file in examples/ is an exec script: it navigates, gives the page one or more goals, and returns the extracted data, which the CLI prints. A goal or an extraction that fails makes the script throw its error. Jev is used through the gateway, so AI_GATEWAY_API_KEY is the only key needed. With DEBUG=browserless:agent, each goal also logs one line with its status, accuracy, cost and timing. The examples call profiling() for every goal whether or not the line is printed, so each goal makes the one evaluation request.
| Script | Steps |
| examples/wallapop.js | Search bmw x3; sort by lowest price; extract the products | | examples/wikipedia.js | Search for an article and open it; extract title and first paragraph | | examples/google-flights.js | Reject cookies if asked; find one-way Zurich to London flights 30 days from today; extract the flights | | examples/hacker-news.js | Open the comments of the first story; extract title, points and comments | | examples/github.js | Open the open issues of this repository; extract them | | examples/run.js | Any page: --url= --goal= --extract= |
--no-headless opens a visible browser window, so every step the agent takes can be watched. Without it the browser runs headless.
npm start runs the Wallapop one. All six were run as shipped on a paid gateway account and returned data matching their goal: 32 Wallapop products sorted by lowest price, the Wikipedia title, 48 flights with prices, a Hacker News story with its points and comments, 4 GitHub issues, and Alan Turing. That is a check that they can work, not a reliability figure. What went wrong along the way:
• Wikipedia's first paragraph was never extracted: the first on the page is empty and a rule reads the first match. • Google Flights shows a cookie consent page in the EU, hence its first goal, and navigates with the browserless adblocker off because the adblocker leaves that page blank. One of its two final runs failed when the AI SDK refused a decision whose chosen option was not the most probable. • One Wallapop run failed when the gateway took over 25 seconds to answer. • Model requests are not retried, so one slow or refused answer ends a run.
API
await page.goal(goal, options?)
Resolves to { status, steps, decisions, trace, profiling }, plus error when status is 'error':
status is 'success' when the model reports visible satisfaction of the goal, and 'error' when the run stopped for any other reason; error then says why. goal does not throw for a run that fails. It throws only when it is called wrong: no page, an empty goal, an invalid option, or a goal already running on the page. Success is a model judgment, not an independent proof of correctness. Each trace entry has the operation, snapshot action ID, operation confidence/probabilities, selected target confidence/probabilities, step/request counts, stale status and whether the page changed. Text-entry values are recorded too; treat traces as private data.
Call profiling to get what the run cost, how long it took, and a model's verdict on whether the goal was met. It is there for failed runs too:
cost and timing come from what each model call already returned, with no extra request: tokens from the AI SDK usage, dollars from the AI Gateway providerMetadata.gateway.cost, and generationIds to look calls up in the gateway. usd, inputTokens and outputTokens are undefined when any call did not report them, such as a model outside the gateway, so a total is never understated. The cache and reasoning breakdowns count only the calls that report them; decision models report none. otherMs is the run time not spent waiting on a model: observing, acting, settling and waits.
accuracy is the one extra request: the evaluator model reads the final page, its fields, and the actions taken, without the run's own DONE, and answers whether the goal is met. probability is its probability that it is. It is a second model judgment, not ground truth: the default evaluator, 'typesafe-ai/jev', is the same model that takes the decisions by default. Its cost is included in cost and its time in evaluationMs, not totalMs. Calling profiling() sends the page text and typed values to the evaluator's provider.…
Description from the npm listing.
- agent
- ai-sdk
- browserless
- jev
- puppeteer
Where @browserless/agent sits in the listing
Each band is one page of 20. Weekly downloads on a log scale. Placement is projected from weekly downloads, so it can differ from the marketplace's own sort order. Hover a dot to see the listing.


Charts
Images: 30d · 1y · all time · 1600×900 dark
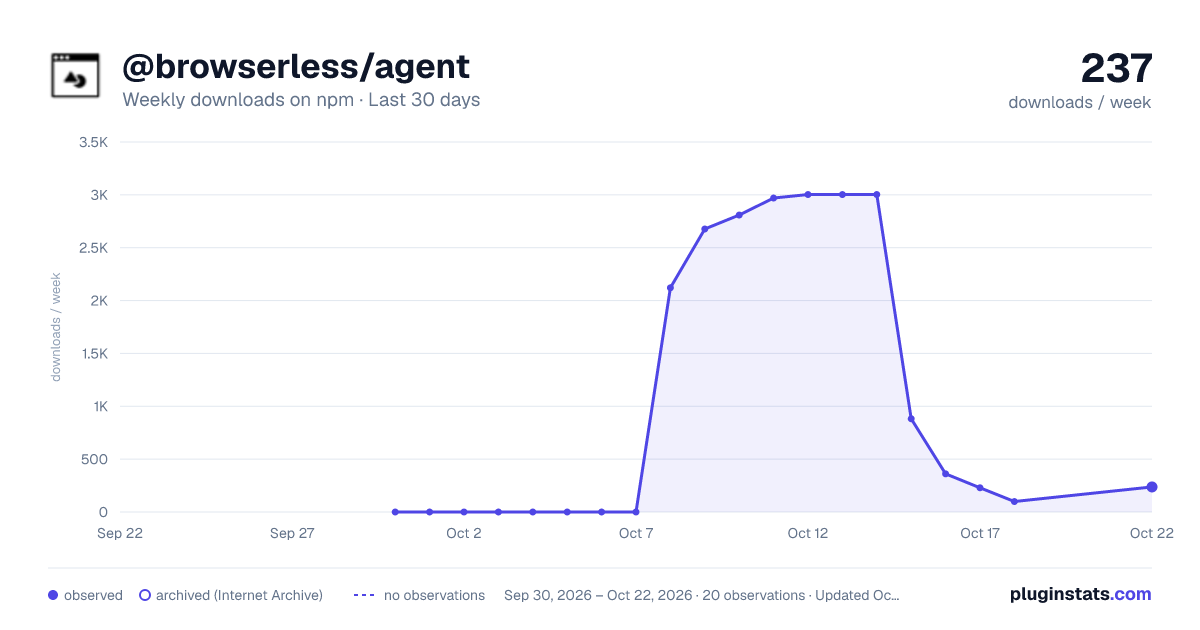
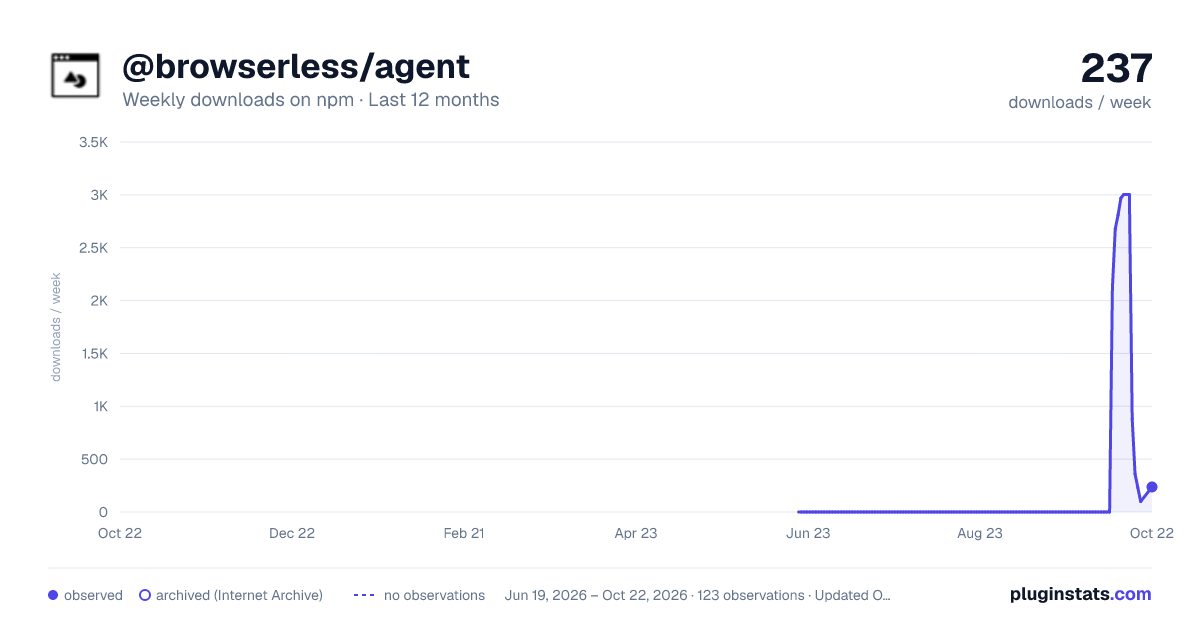
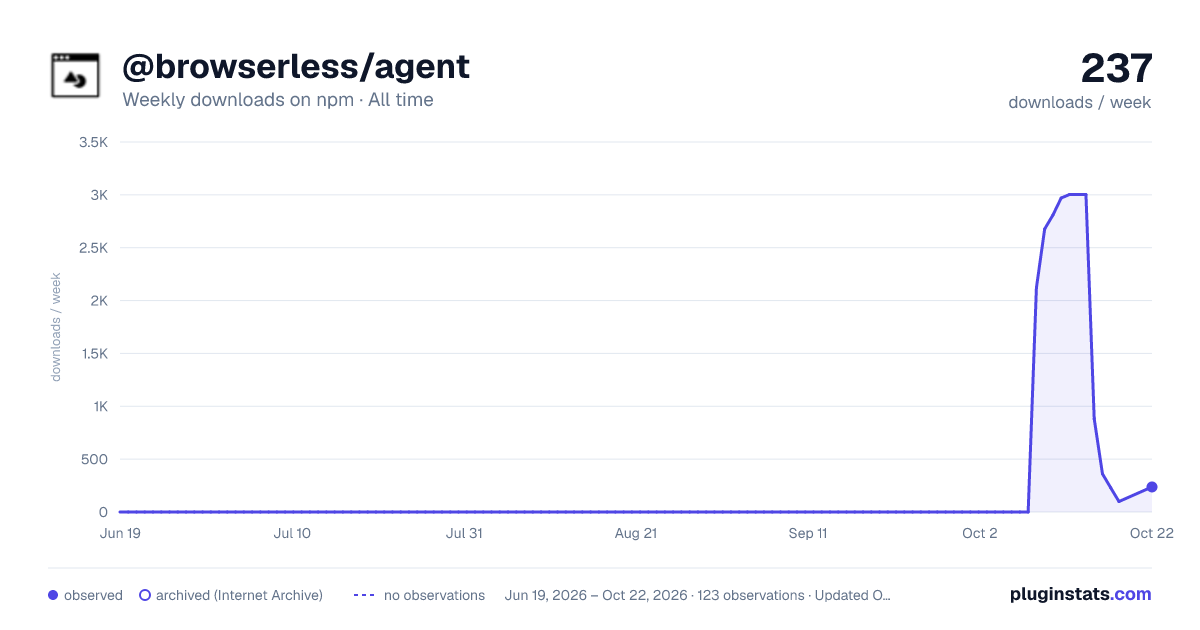

Adoption over time


7/30/90-day growth


Filled points are observed values; hollow points come from Internet Archive snapshots of the listing page. Dashed segments span periods with no observations — values between points are not interpolated.
Recent observations
Full history (121)Similar npm AI SDKs plugins
Data source
Weekly downloads (trailing 7 complete days) come from the official npm downloads API. Downloads include CI and mirrors and are not equivalent to installs or users. npm publishes no ratings.
Listing: https://www.npmjs.com/package/@browserless/agent. First seen Oct 16, 2026; last successful collection Oct 18, 2026. See the methodology.