 PluginStats
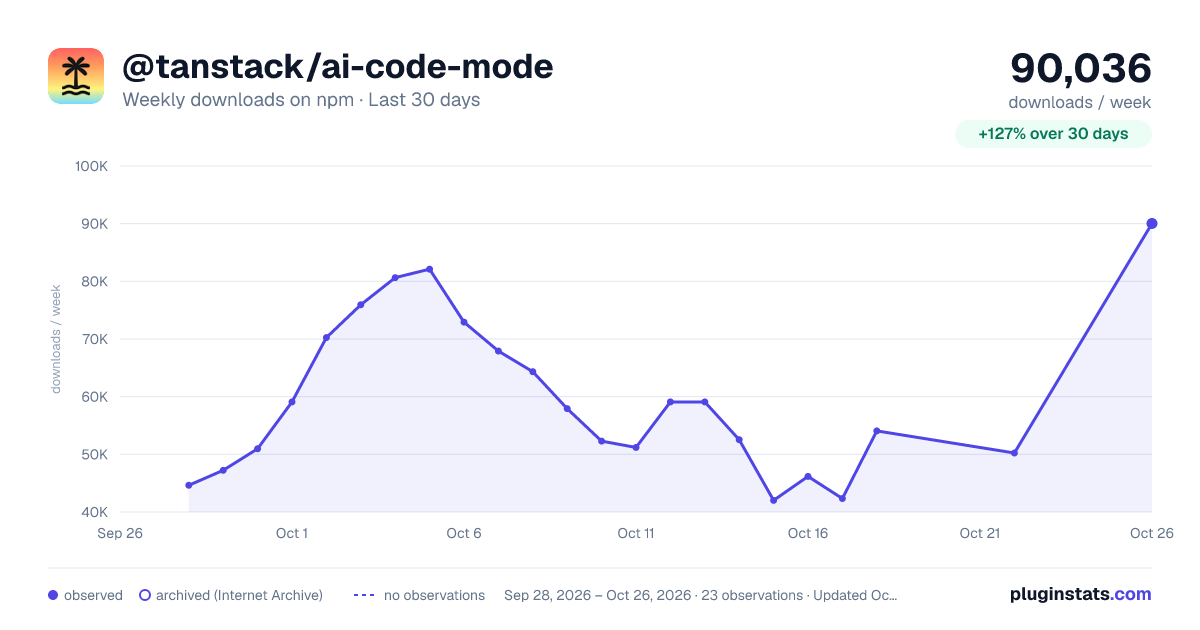
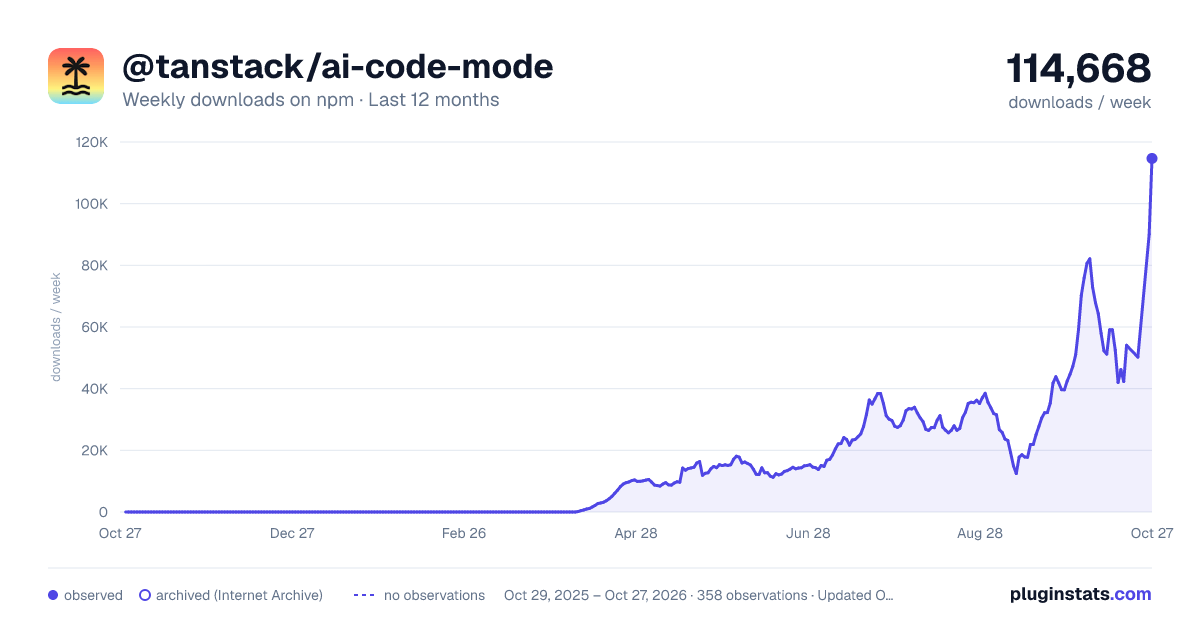
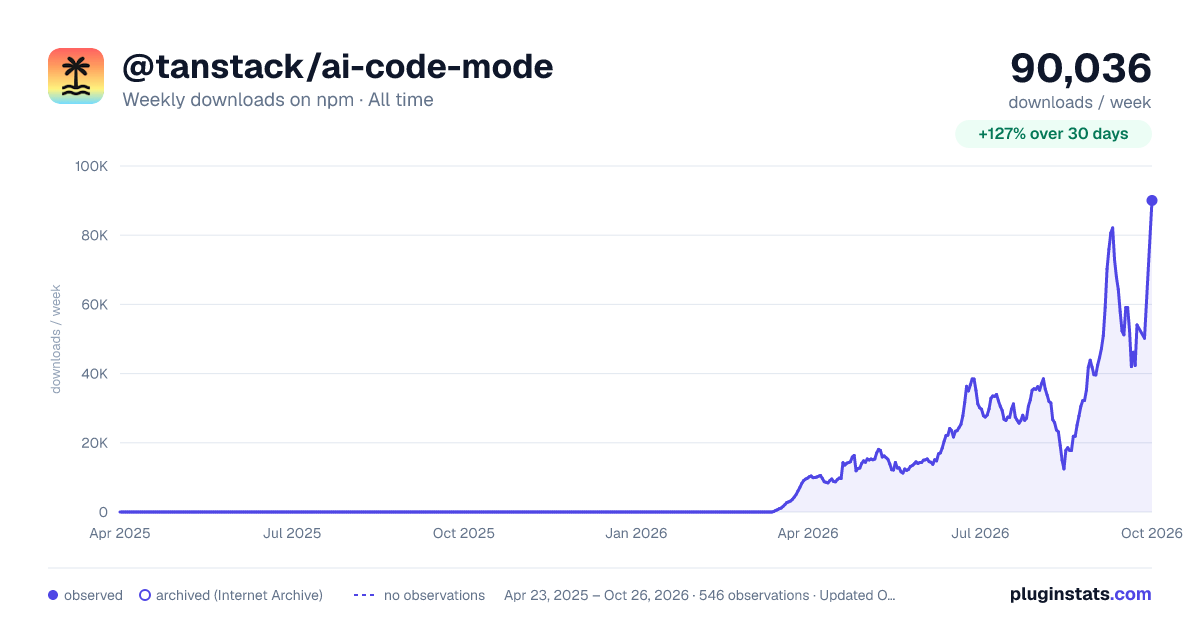
@tanstack/ai-code-mode has 42,338 recorded weekly downloads on npm, an increase of 52.6% over the past 30 days.
It ranks #595 of 2,251 tracked npm listings by weekly downloads.
Over 90 days, weekly downloads changed by +16.6%.
PluginStats has 543 daily observations since Apr 23, 2025; the latest is from Oct 17, 2026.
About @tanstack/ai-code-mode
@tanstack/ai-code-mode
Code Mode for TanStack AI — let LLMs write and execute TypeScript in secure sandboxes with typed tool access.
Overview
Code Mode gives your AI agent an execute_typescript tool. Instead of one tool call per action, the LLM writes a small TypeScript program that orchestrates multiple tool calls with loops, conditionals, Promise.all, and data transformations — all running in an isolated sandbox.
Installation
You also need an isolate driver:
Quick Start
The LLM will generate code like:
API Reference
createCodeMode(config)
Creates both the execute_typescript tool and its matching system prompt. This is the recommended entry point.
Config:
• driver — An IsolateDriver (Node, QuickJS, QuickJS Bun, or Cloudflare) • tools — Array of ServerTool or ToolDefinition instances. Exposed as external_* functions in the sandbox • timeout — Execution timeout in ms (default: 30000) • memoryLimit — Memory limit in MB (default: 128, supported by the Node, QuickJS, and QuickJS Bun drivers) • getSnippetBindings — Optional async function returning dynamic bindings
createCodeModeTool(config) / createCodeModeSystemPrompt(config)
Lower-level functions if you need only the tool or only the prompt. createCodeMode calls both internally.
Advanced
These utilities are used internally and exported for custom pipelines:
• stripTypeScript(code) — Strips TypeScript syntax using sucrase (edge-safe, no native binary). • toolsToBindings(tools, prefix?) — Converts tools to ToolBinding records for sandbox injection. • generateTypeStubs(bindings, options?) — Generates TypeScript type declarations from tool bindings.
Driver Selection Guide
| Driver | Best For | Native Deps | Browser | Memory Limit |
| @tanstack/ai-isolate-node | Server-side Node.js apps | Yes (isolated-vm) | No | Yes | | @tanstack/ai-isolate-quickjs | Browser, edge, or no-native-dep environments | No (WASM) | Yes | Yes | | @tanstack/ai-isolate-quickjs-bun | Bun servers (native QuickJS via bun:ffi) | No | No | Yes | | @tanstack/ai-isolate-cloudflare | Cloudflare Workers deployments | No | N/A | N/A |
Custom Events
Code Mode emits custom events during execution that you can observe via the TanStack AI event system:
| Event | Description |
| code_mode:execution_started | Emitted when code execution begins | | code_mode:console | Emitted for each console.log/error/warn/info call | | code_mode:external_call | Emitted before each external_* function call | | code_mode:external_result | Emitted after a successful external_* call | | code_mode:external_error | Emitted when an external_* call fails |
Models eval (development)
The benchmark lives in a separate workspace package so @tanstack/ai-code-mode does not depend on @tanstack/ai-isolate-node (avoids an Nx build cycle). See models-eval/package.json (@tanstack/ai-code-mode-models-eval).
1. packages/ai-code-mode/models-eval/pull-models.sh — pull recommended Ollama models 2. pnpm --filter @tanstack/ai-code-mode-models-eval eval:capture — run models and capture raw outputs/telemetry only (no judge LLM call) 3. pnpm --filter @tanstack/ai-code-mode-models-eval eval:judge — judge latest captured session from logs (no model rerun) 4. pnpm --filter @tanstack/ai-code-mode-models-eval eval — single-pass run+judge (legacy convenience mode) 5. pnpm --filter @tanstack/ai-code-mode-models-eval eval -- --ollama-only — only Ollama models from eval-config.ts 6. pnpm --filter @tanstack/ai-code-mode-models-eval eval -- --ollama-only --models qwen3-coder — one or more model ids (comma-separated)
Judge-phase flags:
• --judge-latest judge latest captured session • --rejudge re-run judging even if logs already contain judge fields
The default list omits some small Ollama models that rarely complete code-mode successfully (see comments in eval-config.ts). You can still benchmark them with --models granite4:3b etc. if pulled locally.
Model comparison metrics
The models eval now tracks seven decision-oriented metrics plus an overall rating:
• accuracy (1-10): numerical/factual correctness vs gold report • comprehensiveness (1-10): whether the response covers everything requested by the user query • typescriptQuality (1-10): quality/readability/type-safety of generated TypeScript • codeModeEfficiency (1-10): how efficiently the model uses code-mode/tooling to reach the answer • speedTier (1-5): relative wall-clock speed against peers in the same category (local or cloud) • tokenEfficiencyTier (1-5): relative token efficiency against peers in the same category • stabilityTier (1-5): success consistency over the latest 5 logged runs for that model • stars (1-3): weighted rollup score across all metrics
Raw run telemetry also includes compile/runtime failures, redundant schema checks, total tool calls, TTFT, token totals, stability sample size/rate, and per-model logs.
Methodology
Canonical output is written to packages/ai-code-mode/models-eval/results.json after each capture or judge run.
• Benchmark: single code-mode benchmark prompt over the in-memory customers / products / purchases dataset • Primary quality scores (judge): accuracy, comprehensiveness, typescriptQuality, codeModeEfficiency • Computed comparative scores: speedTier, tokenEfficiencyTier, stabilityTier • Stability definition: a run is "stable" if it has no top-level run error, produces a non-empty candidate report, and has at least one successful execute_typescript call • Star rollup weights: • accuracy: 25% • comprehensiveness: 15% • typescriptQuality: 15% • codeModeEfficiency (with compile/runtime failure penalty): 10% • speedTier: 10% • tokenEfficiencyTier: 10% • stabilityTier: 15%
Model comparison table
The table below is transcribed from canonical models-eval/results.json (session 2026-03-26T15:38:44.006Z).
| Provider | Model | Category | Stars | Accuracy | Comprehensiveness | TypeScript | Code-Mode | Speed Tier | Token Tier | Stability Tier |…
Description from the npm listing.
- ai
- ai-sdk
- typescript
- tanstack
- code-mode
- agents
- llm
- tool-calling
- sandbox
- isolate
- code-execution
- tanstack-intent
Where @tanstack/ai-code-mode sits in the listing
Each band is one page of 20. Weekly downloads on a log scale. Placement is projected from weekly downloads, so it can differ from the marketplace's own sort order. Hover a dot to see the listing.


Charts
Images: 30d · 1y · all time · 1600×900 dark

Adoption over time


7/30/90-day growth


Filled points are observed values; hollow points come from Internet Archive snapshots of the listing page. Dashed segments span periods with no observations — values between points are not interpolated.
Recent observations
Full history (543)Similar npm AI SDKs plugins
Data source
Weekly downloads (trailing 7 complete days) come from the official npm downloads API. Downloads include CI and mirrors and are not equivalent to installs or users. npm publishes no ratings.
Listing: https://www.npmjs.com/package/@tanstack/ai-code-mode. First seen Oct 16, 2026; last successful collection Oct 18, 2026. See the methodology.