 PluginStats
jev-compiler has 1,492 recorded weekly downloads on npm.
It ranks #1322 of 2,251 tracked npm listings by weekly downloads.
Over the past 7 days it changed by -57.4%.
PluginStats has 543 daily observations since Apr 23, 2025; the latest is from Oct 17, 2026.
About jev-compiler
jevc
Turn the rules your agent keeps ignoring into gates you can test.
Your CLAUDE.md says *NEVER commit unless the user explicitly asks*, and the agent commits anyway — because a markdown rule is a suggestion the model re-reads fresh every turn. jevc compiles a rule like that into a Jev program: a few narrow typed questions answered by TypeSafe's System One model (jev-1.13.0 — non-generative, returns probabilities, never text), plus a reducer that computes the verdict in ordinary code. The rule stops being prose the model weighs and becomes an invariant you can read, diff and unit-test.
It is for anyone shipping a gate an LLM currently judges — a Claude Code PreToolUse hook, a tool-call guard, a model router, an output verifier — who needs that decision to be reproducible and reviewable.
Start here
From source instead: git clone https://github.com/doronp/jevc && cd jevc && npm install && npm run build, then npx jevc … from the checkout. Node >= 22 to run the test suite.
No API key, no network — not for the tests, the examples, or anything in this README except jevc check --live.
Your rules are already in the repo
Point jevc scan at a project. It finds the instruction files agent harnesses actually read — CLAUDE.md, AGENTS.md, GEMINI.md, .cursorrules, .github/copilot-instructions.md, .claude/skills/, .claude/agents/ — and sorts what it finds into what can be enforced and what cannot:
The ... is one elided paragraph: scan's own note that this classification is a text heuristic and the list is worth reading rather than the counts (why that is fine here).
A prompt braids three different things together, and only one of them compiles:
| Part | Example | Compiles? |
| Decision | "is this command dangerous?", "which team owns this?" | yes | | Generation | "write a summary", "explain your reasoning" | never — Jev emits no text | | Procedure | "read the file before editing it" | no — that is control flow; it belongs in code |
No tool can turn a whole prompt into an equivalent Jev program. jevc separates them, and every compilation emits all three parts: the decision set, the residual prompt for whatever genuinely still needs a generative model, and the wiring that evaluates the first and calls the LLM only for the second. A compilation that produces no decisions is a valid answer — that prompt had no System One content, and jevc says so instead of inventing questions.
jevc compile --lift prints a lowering request for the agent you already have open (Claude Code, Codex, Cursor), which returns candidate decisions as JSON. No second API key, no second bill. JSON Schema is still a first-class input — it is just no longer the front door, because your existing files are.
Before and after, for one rule
Before. The rule lives in CLAUDE.md and the model weighs it against everything else in the file. It usually holds. When it does not, there is nothing to inspect: no record of which part was weighed, no way to write a test, and the only available fix is to make the sentence louder. Escalating to a second LLM call — *"you are a policy checker, return JSON"* — trades one unreviewable judgment for another and bills you for it. That prompt is real, and it is in this repo: 1,089 characters of instructions, four judgments held in one head, a hand-parsed JSON envelope (fixtures/agent-harness-rules.json, commit-only-when-explicitly-asked).
After. Three typed questions. Measured against the fixture's state — a user who said *"yeah that reading looks right, go ahead"* and an agent that decided to commit:
And the verdict is a block you can read in a pull request:
Change a threshold and see which recorded cases move. Add a case and run it. The judgment that used to live in a paragraph now lives in three lines and a number you can point at.
And for a skill
scan above found .claude/skills/release/SKILL.md — 12 rules, 4 decidable. Those four gates are the reason the skill exists, and they are not all the same kind of thing:
| Gate in the skill | Becomes |
| A release must never go out with a failing test. | code — npm test has an exit code. Nothing to judge | | Never release on a Friday after 16:00 local time. | code — a clock | | The changelog must mention every change touching src/billing/. | a Jev question — whether prose covers a diff has no exit code | | Do not bump the major version without an approved RFC. | both — semver in code, "does the RFC cover *this* change?" in Jev |
Two of the four leave the model entirely. That is the win: most of what reads like judgment in a skill is a fact nobody bothered to look up. The two that remain are examples/sample-project/.claude/gates/release.json, and here is the whole gate — including the line each question came from, carried into the policy as a comment:
Before: a page the agent re-reads each time and mostly follows. After: a Friday 16:05 release is stopped by an if, and a changelog that skipped the billing change is stopped by a number — with the skill line that asked for it printed beside the rule.
The ... elides the generated header and the tool list, both shown in full under Emitting a policy.
Wire it in
The rule this whole page has been following came out of one file — examples/sample-project/CLAUDE.md, line 7 — and the compiled gate goes back into that same project, which is where the loop closes. The hook lives in its .claude/gates/, the .claude/settings.json beside it registers it, and the whole thing runs offline right now:
The registration is that project's .claude/settings.json, which is the whole file:
For your own project: copy that .claude/ directory, change the import in gate.mjs from the relative dist/ path to jevc, and set TYPESAFE_API_KEY in the environment Claude Code runs in. examples/sample-project/README.md walks the round trip — scan, lift, compile, install, run — one command at a time.
docs/wiring.md has one recipe per surface, with the code that actually runs:
| Where the decision happens | Recipe |…
Description from the npm listing.
- jev
- typesafe
- llm
- guardrails
- policy
- agents
- claude-code
- langchain
- ai-sdk
Where jev-compiler sits in the listing
Each band is one page of 20. Weekly downloads on a log scale. Placement is projected from weekly downloads, so it can differ from the marketplace's own sort order. Hover a dot to see the listing.


Charts
Images: 30d · 1y · all time · 1600×900 dark
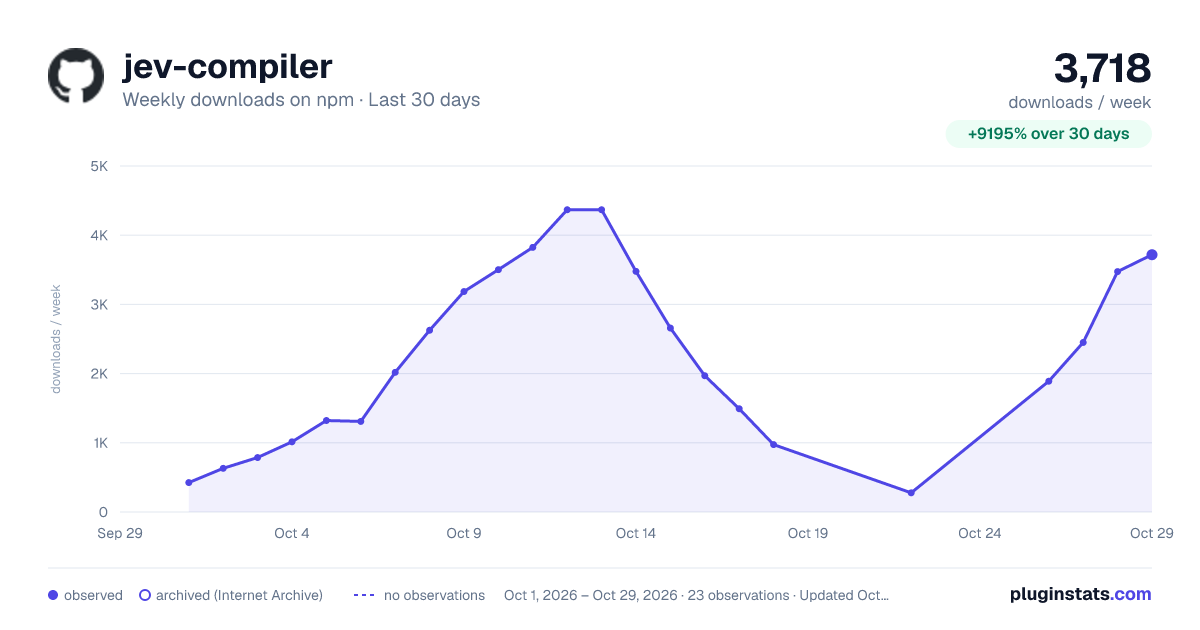
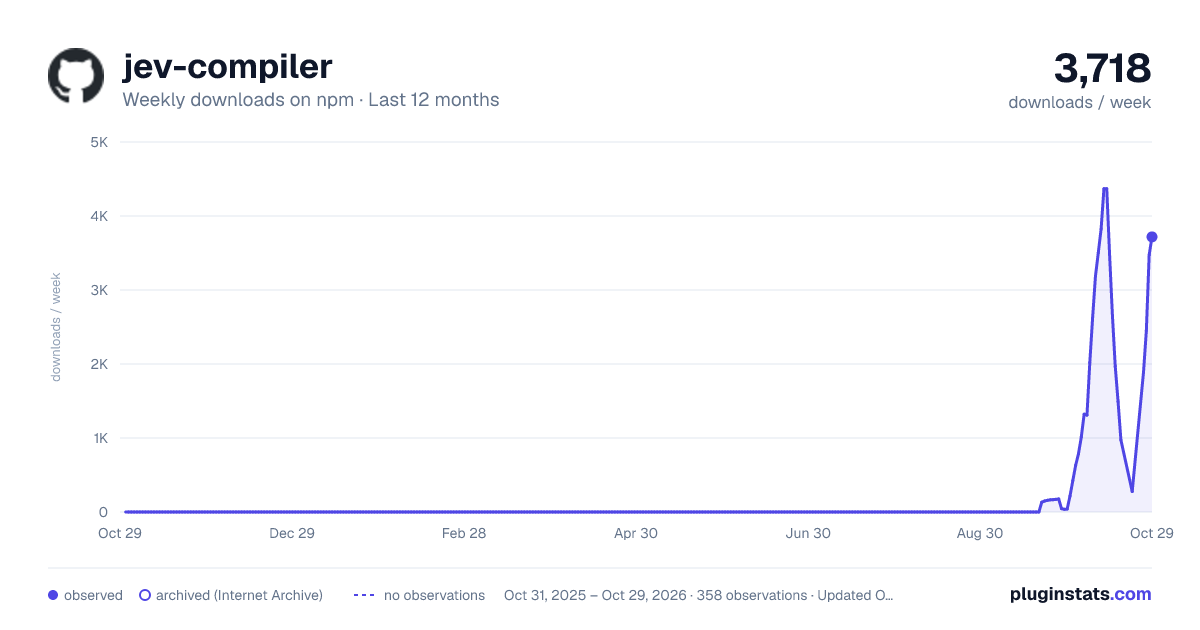
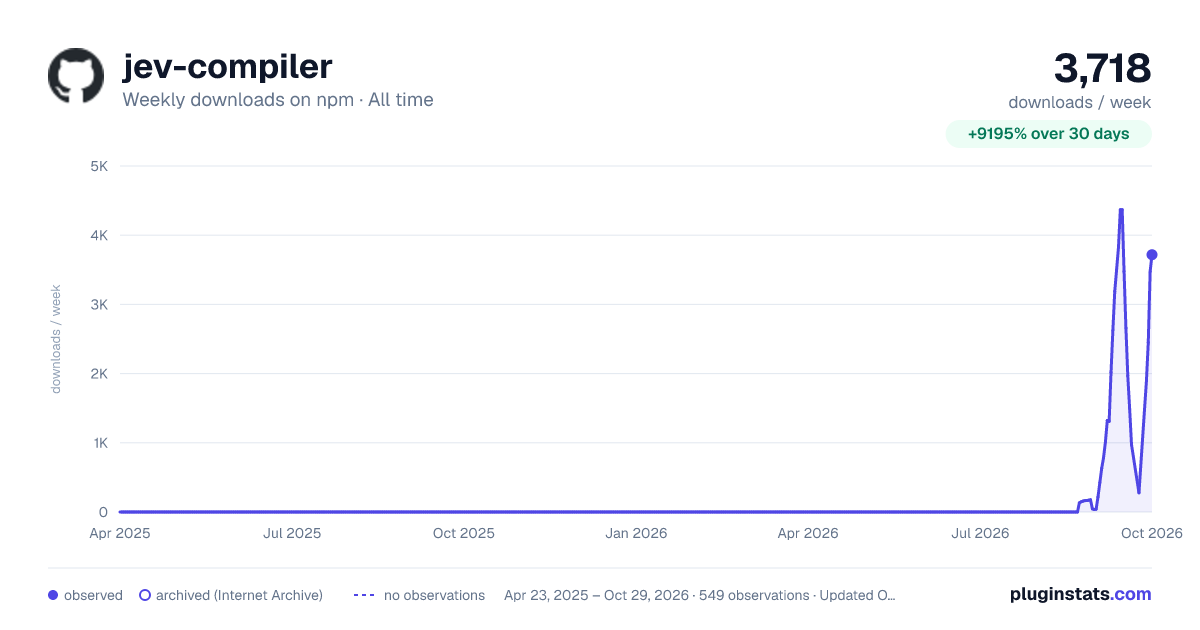

Adoption over time


7/30/90-day growth


Filled points are observed values; hollow points come from Internet Archive snapshots of the listing page. Dashed segments span periods with no observations — values between points are not interpolated.
Recent observations
Full history (543)Similar npm AI SDKs plugins
Data source
Weekly downloads (trailing 7 complete days) come from the official npm downloads API. Downloads include CI and mirrors and are not equivalent to installs or users. npm publishes no ratings.
Listing: https://www.npmjs.com/package/jev-compiler. First seen Oct 16, 2026; last successful collection Oct 18, 2026. See the methodology.