 PluginStats
@brightdata/mcp weekly downloads statistics
By brightdata (2 listings) · npm · MCP servers
An MCP interface into the Bright Data toolset
@brightdata/mcp has 8,687 recorded weekly downloads on npm, a decrease of 28.3% over the past 30 days, ranking #946 of 2,256 tracked listings.
About @brightdata/mcp
Bright Data MCP
Web search, page scraping, structured data extraction, and browser automation for AI agents and LLMs over the Model Context Protocol.
Works with AI agents, coding agents, chat assistants, and any MCP-compatible client.
Quick Start • Pricing • Use Cases • Tools • Agent Skills • Docs • Support
Free tier: 5,000 requests per month. No credit card required. Renews monthly.
Overview
The Bright Data MCP server gives AI agents real-time access to public web data. It exposes 32 tools covering:
• Web search — Google, Bing, and Yandex results as structured data • Page scraping — any URL as Markdown or HTML, with bot detection, CAPTCHA solving, and proxy rotation handled automatically on every request • Structured data (Web Scraper API) — clean JSON from 1,200+ pre-built scrapers: Amazon, LinkedIn, Instagram, TikTok, YouTube, X, Reddit, Facebook, Crunchbase, Zillow, npm, PyPI and more, without parsing HTML. Six tools find and run any of them • Browser automation — navigate, click, type, screenshot, and read pages in a remote browser session • LLM response collection — send prompts to ChatGPT and Perplexity and get their answers back as structured data
Every request is routed through Bright Data's unblocking infrastructure, so pages that block ordinary HTTP clients (bot detection, CAPTCHAs, rate limits, geo-restrictions) return normally. No proxy setup, no headless browser maintenance, no retry logic to write.
Two deployment options: a hosted remote server (one URL, no installation) or a local instance via npx @brightdata/mcp.
Quick Start
Hosted server — no installation. Add this URL to your MCP client:
Get your API token from your Bright Data account settings. New accounts get 5,000 free requests per month.
Optional URL parameters:
| Parameter | Description | Example |
| groups= | Limit to specific tool groups (default: all tools) | ...&groups=scrapers,browser | | tools= | Limit to specific tools | ...&tools=search_engine,scrape_as_markdown |
Claude Desktop
- Go to: Settings → Connectors → Add custom connector 2. Name: Bright Data 3. URL: https://mcp.brightdata.com/mcp?token=YOUR_API_TOKEN 4. Click "Add"
Or run locally:
Claude Code
Cursor
Add to ~/.cursor/mcp.json:
VS Code
Add to .vscode/mcp.json:
Windsurf
Add to ~/.codeium/windsurf/mcp_config.json:
Gemini CLI
Add to ~/.gemini/settings.json:
Zed
Add to your Zed settings:
Warp
Go to Settings > MCP Servers > Add MCP Server and add:
Other clients (local npx)
For any client that supports local MCP servers:
Pricing and Free Tier
Every account includes a recurring monthly free tier. No credit card or commitment required to start.
5,000 free requests per month, renewing on the 1st of each month. Unused requests don't roll over. For team accounts, the free tier is shared across all users in the account.
What's included free:
• Fetch any webpage and extract as Markdown • Access to 60+ pre-built scrapers for popular domains • Web search (Google, Bing, Yandex) • Web unlocking (bot detection bypass, CAPTCHA solving, proxy rotation) • Browser automation • Geo-targeting
Beyond the free tier — pay as you go, no commitment:
| | Search, Scrape & Extract | Browser Navigation |
| Pay as you go | $1.50 / 1K results | $8 / GB |
• When free requests run out, requests stop. No surprise charges — unless you have deposited funds • Adding a credit card is a verification step only; you are not charged unless your free tier is exhausted and you have funds deposited • Set a spend cap in the control panel so pay-as-you-go usage never exceeds your budget
Full pricing, volume plans and enterprise →
Use Cases
Real-time research
Answer questions using live web data instead of training data. Search, then read the sources.
| Task | Tools |
| Search the web for current information | search_engine, search_engine_batch | | Read a specific page as clean Markdown | scrape_as_markdown, scrape_batch |
Example prompts: "What's Tesla's current stock price?", "Get today's weather forecast for New York", "Find the most cited sources on EU AI regulation from the last 6 months".
E-commerce intelligence
Read product data as structured JSON: price, availability, rating, review count, seller, images.
| Task | Tools |
| Products, reviews and search results from Amazon, Walmart, eBay, Best Buy, Etsy, Home Depot, Zara and other stores | search_scrapers → get_scraper_details → run_scraper | | Cross-retailer price view | the same flow with the Google Shopping scraper |
Example prompts: "Compare this laptop's price on Amazon vs Walmart vs Best Buy", "Get the rating and review count for ASIN B0D2Q9397Y", "Is this product in stock?".
Market and competitor analysis
Build competitor profiles from live data: funding, headcount, hiring, customer reviews, pricing pages.
| Task | Tools |
| Company funding, size, employees, job postings (Crunchbase, ZoomInfo, LinkedIn) | search_scrapers → run_scraper | | Customer sentiment (Google Maps, Facebook, app store reviews) | search_scrapers → run_scraper | | Competitor pricing pages | scrape_as_markdown, scrape_batch | | Market discovery | search_engine_batch |
Example prompt: "Analyze Notion as a competitor: pricing, funding, hiring focus, and what customers complain about".
AI agents with reliable web access
Replace built-in fetch/search tools that get blocked on protected sites. Every request goes through unblocking infrastructure, so agents don't fail on bot detection, CAPTCHAs, or geo-restrictions.
| Task | Tools |
| Drop-in replacement for built-in web search | search_engine | | Drop-in replacement for built-in URL fetch | scrape_as_markdown | | Parallel data collection (10 at a time) | search_engine_batch, scrape_batch | | Interactive sites (login walls, infinite scroll, dynamic content) | scraping_browser_* (14 tools) | | Structured JSON from any page, no schema needed | extract |
Coding agents
Package registry data on demand — no scraping, no stale caches.
| Task | Tools |…
Description from the npm listing.
- mcp
- brightdata
README badge
Show your rank in a README or on your website. The badge updates automatically.
Charts
Images: 30d · 1y · all time · 1600×900 dark
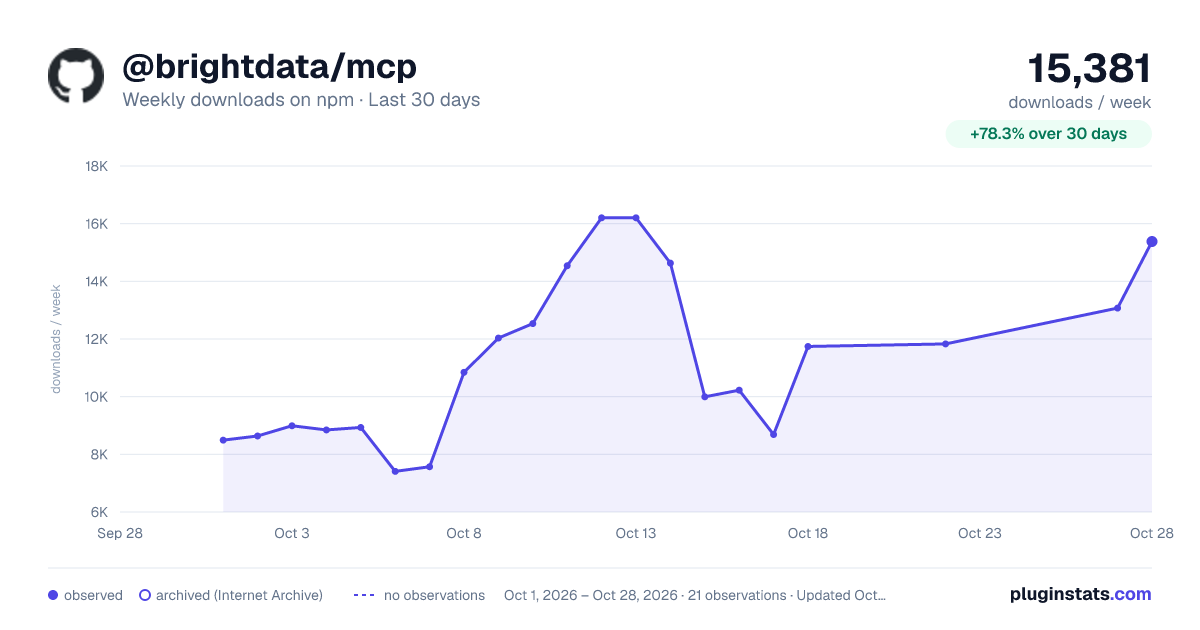
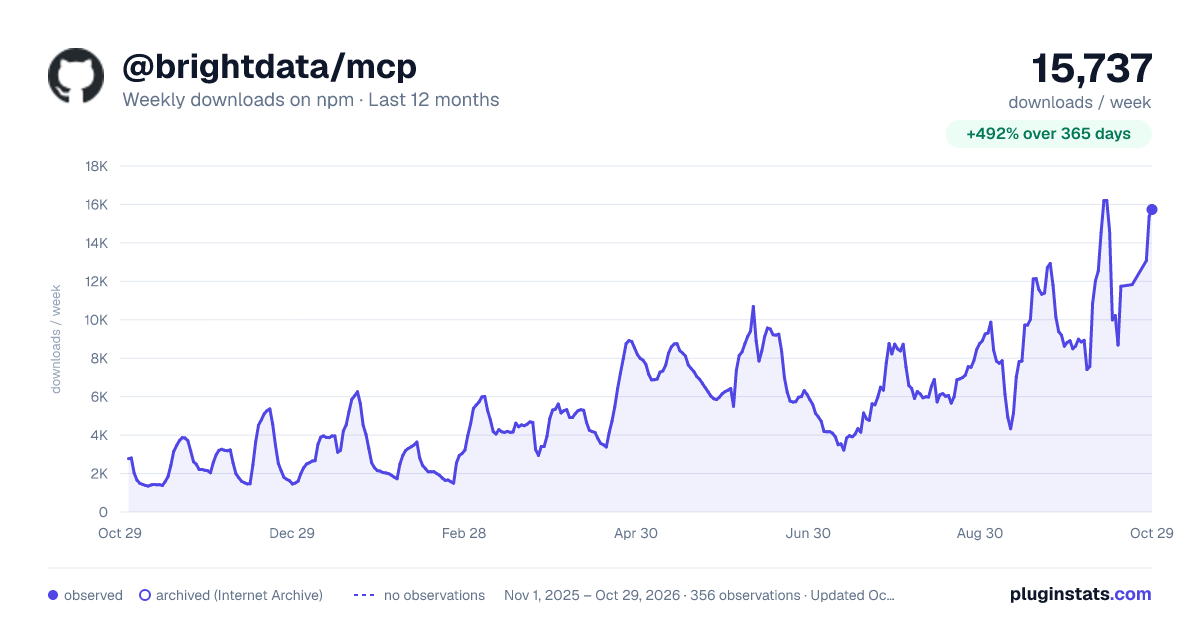
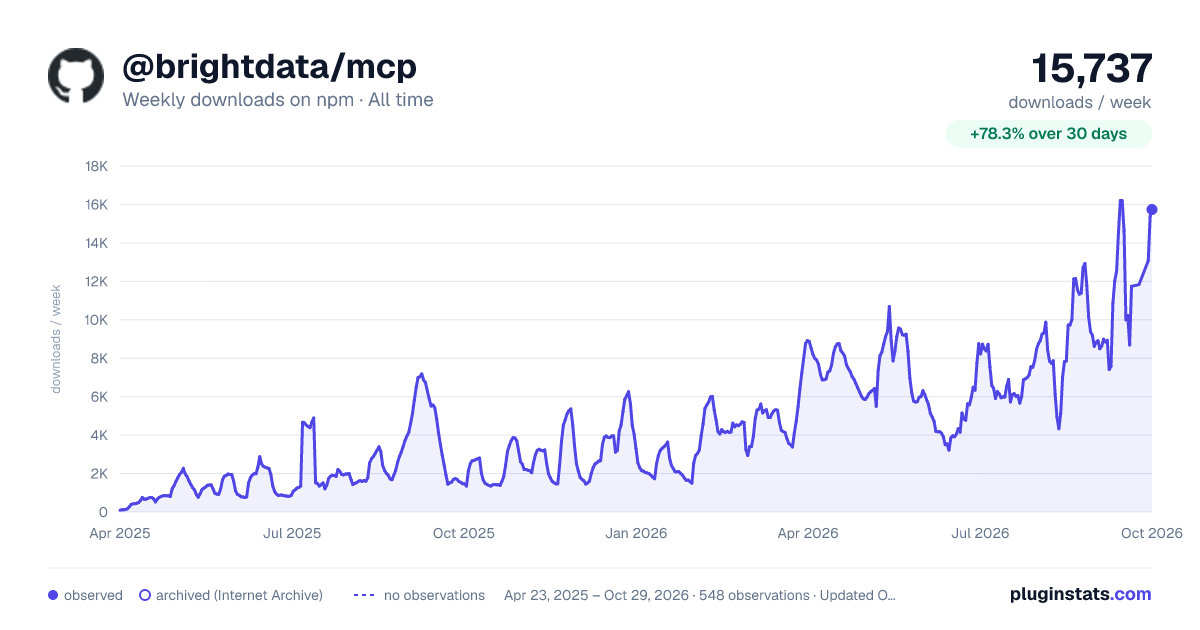

Adoption over time
7/30/90-day growth
Ranking history
Listing placement
Listing placement
Filled points are observed values; hollow points come from Internet Archive snapshots of the listing page. Dashed segments span periods with no observations — values between points are not interpolated.
Each band is one page of 20. Weekly downloads on a linear scale. Placement is projected from weekly downloads, so it can differ from the marketplace's own sort order. Hover a dot to see the listing.
Recent observations
Full history (543)Similar npm MCP servers plugins
All 20 @brightdata/mcp alternativesData source
Weekly downloads (trailing 7 complete days) come from the official npm downloads API. Downloads include CI and mirrors and are not equivalent to installs or users. npm publishes no ratings.
Listing: https://www.npmjs.com/package/@brightdata/mcp. First seen Oct 16, 2026; last successful collection Oct 19, 2026. See the methodology.